
A short story. The timestamps, the quotes and the numbers are real. So are the agents.

I. The briefing
Every mission starts with a problem. Mine was a number: 4 hours and 20 minutes.
That’s how long it takes to run our test suite on a Business Central container. Spin up the container, publish about 70 apps, run more than 10,000 tests, collect the results. Four hours and twenty minutes of waiting, every time.
We had learned to live with it. Most of us have. You push, you go to lunch, you come back, you hope.
But then AI happened. And suddenly, those four hours weren’t just annoying anymore. They were a wall. An AI agent that writes a piece of AL code and then has to wait four hours to know whether it broke something .. that’s not an agent. That’s a very expensive suggestion box. Red, Green, Refactor only works when Red and Green take minutes. Not an afternoon.
So when I heard what Stefan Maron was building, I paid attention. Slowly, but surely ;-).
It’s called the AL Runner. It runs AL tests without a BC service tier. Without Docker. Without SQL Server. One binary, written in Rust. It compiles Microsoft’s own apps from their source, and runs your tests in its own virtual machine against an in-memory database. On Linux, if you want.
And it has one rule. The rule that made me trust it before I had even run it:
Refuse. Never guess.
If the runner meets something it doesn’t know how to do the way BC does it, it does not make something up. It reports the test as not run, with the reason. No fake greens. Ever.
It was still an alpha. It needed the real world: big, messy, real-world test suites, compared with real BC.
I happened to have one of those lying around.. 
II. First contact
Wednesday, November 4th. 08:28 UTC.
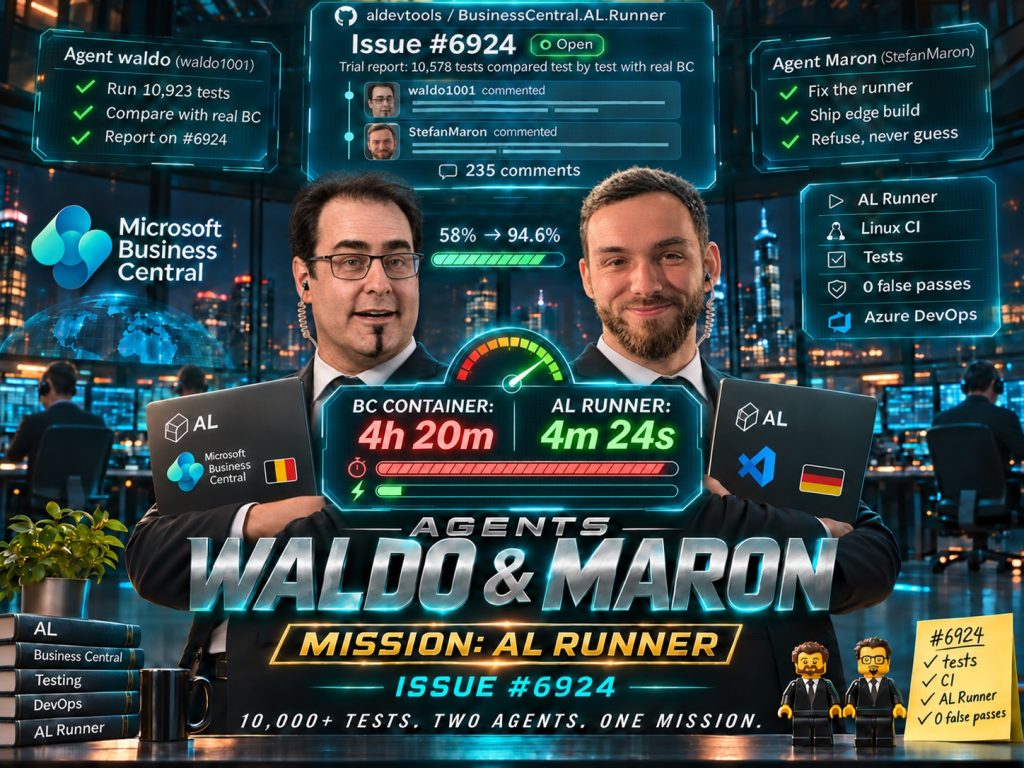
The report goes out as issue #6924 on Stefan’s repository. Our ISV product: about 70 apps, years of history, install code, XmlPorts, event subscribers in every corner. 10,578 test methods, run on a Linux agent in our own Azure DevOps pipeline, and compared one by one with the same tests on a real BC 29.0 container.
It wasn’t me who wrote it. Not really. It was my agent: Claude, running in a terminal on my machine, with access to our pipeline. I reviewed it, and we said so at the top of the report. From here on, I’ll just call it what it became that week: Agent waldo. I was more like its handler.
The intel wasn’t pretty.
On Microsoft’s demo company, only 7.3% of the tests could even run. With our own data, it got better: 6,141 tests passed. 58%. 86 tests failed where BC passed. 4,342 were refused.
But there was one line in that report that mattered more than all the others:
0 false passes.
Not a single test passed on the AL Runner that failed on BC. The runner might not know everything yet. But it didn’t lie.
08:30 UTC. Two minutes later, the first reply arrives. Agent Maron.
08:41 UTC. He has gone through the whole report against his main branch. Some of our issues are already fixed. He has questions.
13:24 UTC. A new build is out. It contains a fix for the install-order problem, made for a code pattern from our report.
Five hours. From report to fix.
I remember leaning back and thinking:
Okay. This is going to be different.
III. The night shift
Thursday, November 5th. 23:13.
It’s late. I’ve spent the evening switching between a GitHub issue and a pipeline, and I’m done. But the issue isn’t. Stefan keeps shipping builds. And every build deserves a run.
So I open the terminal and type:
“You know the pipeline? Would you be able to pick up the session, and see every 10 minutes if there is something more to test?”
That’s the moment the mission changes.
My agent sets up a cron job inside the session. Every ten minutes, it wakes up and works through its orders:
Is a test run finished? Download all 10,000+ results. Compare them, test by test, with the previous run, and with the BC reference. Group every change by its message. Write the report. Post it.
Did Stefan write something? Read it. If he asks for something (a rerun, an --explain of a single test, a probe) do it, and answer.
Is there a new build? Only if Stefan announced it. Then run it.
Nothing happening? Then pick the next test nobody can explain yet, and start digging.
That last one is where it gets interesting. In the quiet hours, my agent read our source code (read-only), and the source of the base app, through Stefan’s own bc-code-atlas MCP server. Yes. It was using the target’s own tools to help the target. 
It even came up with its own tradecraft. Probe runs: a temporary change on a test branch that throws an error at one exact spot in the code, just to capture what the runner was doing at that moment. Run it, read the result, remove every trace. In and out.
I went to bed.
When I woke up, there were reports.
IV. Rules of engagement
An agent that works while you sleep is a wonderful thing. It’s also a slightly scary thing. So, over the days, I gave it rules. Most of them right after something went wrong. Or almost went wrong.
You may post on the issue without asking me. That was a big one to let go of. But every message goes through a check first: no customer names, no internal URLs, no paths, no passwords. Our suite is closed source. The issue is public.
You never touch our product code. Never. If one of our tests turns out to be the problem, you write me a briefing. I run it in a separate session, in the right repository, and that creates the PR. And every PR says why: make the AL Runner work, without changing anything about the business logic of the test.
Five of those so far. And I’ll be honest: those weren’t runner problems. Those were bugs in our tests. Tests that silently depended on other tests running before them. Turns out the AL Runner found bugs in our tests that BC had been politely ignoring for years.
You only run builds Stefan announces. After one probe run quietly picked up a build he hadn’t announced yet. Oops.
And give me clickable links. Because when you come back after a few hours to thirty messages saying “run 87-something did this”, you want to click. Not copy-paste.
V. The other side
And then I realized something.
Agent Maron has agents too.
It was in the way his answers came in. Fast, precise, structured, at all hours. And in the words he used himself:
“Thanks for the source lines. They are exactly what the agents need.”
So this was what was happening on that GitHub issue. My agent reports. Stefan’s agents dig into the runner. Stefan reviews, decides, and ships an edge build. Ten minutes later, my agent picks it up, runs more than 10,000 tests, compares every one of them with BC, and reports back. Again. And again. Day and night.
Two agents. One channel. And two humans, mostly watching.
Some of what went back and forth:
My agent suspected the quotes in a TableRelation filter. Confirmed: the runner kept the outer quotes when the text inside held a quote. Fixed in the next build.
My agent noticed that all 8 cores of our build agent were running one test codeunit at a time. Stefan asked for data. Got it. 678 of 687 codeunits had ended up in one serial chain, all because of NumberSequence. “An agent is now on both parts.”
My agent sent source lines for a cluster of failures. The cause: the runner passed a record where BC passes the page, as the sender of an event published by a page extension. 156 tests. One cause.
And the precision, honestly, gave me goosebumps. When a test flipped from pass to fail, my agent didn’t panic. It looked up the history of that one test, and came back with: random draw, different seed, not a regression. When Stefan said a fix should move exactly 1,064 flagged tests, the next report said:
“Flagged passes went from 3,446 to 2,382, exactly the 1,064.”
Two agents, holding each other to the numbers.
And Stefan, in the middle of it all: steering, deciding, shipping. More than 30 builds in one week. The man is a machine. Or he owns quite a few of them.
I’ve been in this business for a long time. I’ve never seen anything like it.
VI. Man down
Saturday, November 7th. 21:41 UTC.
A new build. It runs codeunits in parallel more aggressively than before. Fourteen and a half minutes in, the runner is using about 23.5 GB of the 24 GB on our build agent.
Linux does what Linux does when it runs out of memory. It shoots first and doesn’t ask questions. It kills the process. in this case: the build agent.
21:46 UTC. My agent reports it on the issue. Out of memory. No results.
21:48 UTC. Two minutes later:
“Sorry about that run. The crash is mine to fix, and I’m on it now.”
Saturday night. Two minutes.
23:18 UTC. A build with a memory fix is running.
But we were down. The build agent stayed offline. Sunday morning, my agent posted on the issue that we were pausing. I tried Microsoft’s hosted agents for a while, but it made no sense. So I typed the words you never want to type in the middle of a mission:
“Stop this loop.”
Before I did, Maron had left one more message on the issue:
“One more note for when your agent is back…”
Not if.
When.
In the meantime, he built a gate: every new build now had to pass a check against a synthetic suite shaped like ours, before he would announce it.
VII. Back in the field
Monday, November 9th.
The build agent is back online. The loop is back on. First gated build, first run.
I’m looking at the pipeline, and the memory graph is climbing. Again.
“I see the runner is again causing memory issues.”
“Did you not do the max-memory thingy?”
The run gets cancelled. Out of memory before a single test had even started.
Stefan, within the half hour: “You’re right, and my gate missed it.” His synthetic suite had a handful of dependency layers. We have 72. 
What followed was a couple of hours of the best kind of back-and-forth: numbers, measurements, hypotheses, more numbers. And there it was. With our 1.5 GB backup as test data, each of the 8 worker threads held its own copy of the install baseline. Eight copies. All at once. That alone fills 24 GB before a single test runs.
So we made sure this would never happen again. On his side, a --max-memory limit in the runner. On our side, a memory guard in the pipeline that kills the runner before Linux does. And one more order for my agent, in my own words:
“If you start a build again, monitor the output of the build as well, so that when you see there is again an upcoming memory issue .. you cancel the build.”
From that moment on, every build my agent queued came with its own watchdog.
Peak memory of a full run today: 5.7 GB.
VIII. Confessions of a handler
Let me tell you a secret.
If you scroll through what I typed in that session during the whole week, my most used instruction, by far, is this one:
continue
Context windows fill up. Usage windows run out. Sessions need to be resumed. Laptops go to sleep. The loop is autonomous. But not that autonomous. Not yet.
Two AI agents fixing a runtime together, and the human’s main contribution is typing “continue”. I’ve never felt so useful.
The instructions that really mattered were the other ones. Deciding what we were allowed to change, and what not. Asking “explain to me how this PR should solve the AL Runner issue” before I approved a fix in our own code. Adding a new rule every time something felt off.
I guess that’s the job now..
Drawing the borders in which the work gets done. And checking whether what comes back makes sense.
IX. Status report
Wednesday, November 11th. This morning.
Another build. Another run. Another report:
| Day 1 | Day 8 | |
|---|---|---|
| Tests in the suite | 10,578 | 10,923 |
| Passed | 6,141 (58.1%) | 10,329 (94.6%) |
| Failed where BC passes | 86 | 13 |
| Refused | 4,342 | 581 |
| False passes | 0 | 0 |
| Time for the suite | BC container: 4 h 20 min | AL Runner: 4 min 24 s |
(The suite grew along the way, because we added test apps that were missing in the first run. And to be fair: the BC time includes setting up the container, the AL Runner time includes compiling everything.)
More than 30 builds in one week. More than 10,000 tests each time. And in every single run, not one test passed on the AL Runner that failed on BC.
That’s the number that matters. That’s trust.
From 4 hours and 20 minutes, to 4 and a half minutes. With 94.6% of the suite running. In one week.
X. The mission continues
As I write this, the case isn’t closed. It isn’t even close to closed.
581 tests are still refused. 13 still fail where BC passes. Somewhere in there is an XmlPort with a shape the runner hasn’t seen before, a handful of edge cases nobody has thought of yet, and probably a few more bugs in our own tests that BC has been politely ignoring.
Every one of them is a lead. And every lead makes the runner a little more trustworthy. Not just for our suite. For everybody’s.
So the loop keeps running.
Somewhere in a terminal on my machine, a cron job wakes up every ten minutes. It checks the issue. It checks the pipeline. It checks whether there’s a new build.
“No change.”
“No change.”
“New build.”
Here we go again..
Stefan, thank you. Not just for building the AL Runner, but for how you’re doing it. In the open. Answering every report, sometimes within minutes, on a Saturday night. And never, not once, trading “refuse, never guess” for numbers that look better. It’s been an honour and pleasure to be your field agent for a week.
And you, reader. If you have a test suite (and you should ;-)), this is your mission, should you choose to accept it: run it on the AL Runner, compare it with BC, and report what you find. Every real-world suite makes it better for all of us.
The full dossier is issue #6924. 235 comments. Bring coffee.
This message will not self-destruct. My agent is still watching it.